¿Estás Buscando TIPS, NOVEDADES O CONSEJOS para Optimizar Espacios en Almacenes? Este es el lugar adecuado.
📌Software reliability check MAGICQA20261109M 08349
Software reliability checks help teams determine whether an application continues to behave correctly under expected workloads, unusual conditions, and routine change. This technical overview uses MAGICQA20261109M as a temporary publication test label, not as a product or quality certification. It explains how to plan reliability testing, collect meaningful evidence, and connect findings to release decisions. The focus is on repeatable methods: defining service expectations, exercising realistic failure conditions, monitoring system behavior, and verifying that quality assurance 08349 processes confirm recovery mechanisms work as intended.
How software reliability checks connect requirements, operation, and recovery
Reliability assurance is the practice of gathering evidence that software performs its intended functions consistently over time. It complements functional testing by examining behavior across repeated requests, extended operation, variable workloads, and disruptions such as unavailable dependencies. A reliability check begins with user and operational expectations, then translates them into observable measures. These can include failure frequency, response-time percentiles, successful transaction rates, data consistency, and time needed to recover. The MAGICQA20261109M label can identify this publication test in a documentation or review workflow; it does not imply that any particular system has been tested or approved.
A useful plan connects each expectation to a test condition and a way to judge the result. For example, if a service must remain available during a dependency interruption, the team can simulate that interruption and observe whether requests fail safely, queues remain bounded, and normal service returns after recovery. Reliability is not established by a single successful run. It requires repeatable checks, controlled environments, documented assumptions, and attention to trends. Teams should also distinguish application failures from infrastructure limitations so that evidence leads to the right corrective action.
How to plan and run a software reliability check
Start with a defined scope rather than a broad goal such as “make the system robust.” Identify the critical user journeys, components, dependencies, and operating conditions that matter most. Agree on measurable acceptance criteria before testing begins, and record the software version, environment, configuration, and test data. A disciplined sequence makes results easier to reproduce and compare. The following steps provide a practical foundation for a reliability exercise, whether it is run before release, during a scheduled resilience review, or after a significant architectural change.
- Set reliability objectives: Specify target availability, acceptable error rates, latency limits, and recovery expectations for critical functions.
- Map failure scenarios: Identify likely faults, including process termination, network delay, dependency outages, resource pressure, and invalid or duplicated requests.
- Prepare a representative environment: Match relevant production settings and workload patterns while using controlled, non-sensitive test data.
- Run repeatable tests: Exercise normal, peak, prolonged, and failure conditions while capturing logs, metrics, traces, and test inputs.
- Review and retest: Compare evidence with acceptance criteria, assign corrective actions, and rerun affected scenarios after changes.
- Defined thresholds make pass and fail decisions more consistent.
- Recorded configurations help another engineer reproduce a result.
- Failure scenarios reveal weaknesses that ordinary functional checks may miss.
- Retesting confirms whether corrective changes improved behavior without creating regressions.
Practical reliability checks for real operating conditions
Practical testing should reflect how an application is actually used without placing uncontrolled risk on live services. A workload model can represent request volume, concurrency, session duration, data size, and the mix of common operations. Engineers can then increase load gradually, hold it at expected levels, and observe whether performance degrades predictably. Long-running tests can expose memory growth, connection leaks, queue accumulation, or gradual deterioration that short tests overlook. For the MAGICQA20261109M publication test, keep this label in the test record only; the technical evidence should identify the system, build, environment, scenario, and measured outcome separately.
Resilience checks should include both the initial fault and the recovery period. If a dependency becomes unavailable, examine whether timeouts prevent requests from hanging, retries avoid overwhelming the dependency, and fallback behavior preserves data integrity. After restoring the dependency, check for a controlled return to normal operation rather than a surge of duplicate work. Monitoring should capture user-visible outcomes alongside internal indicators, because healthy server metrics do not guarantee successful user actions. Each exercise should have clear stop conditions, an owner, and a rollback plan, especially when testing shared environments or resource limits.
- Load behavior: Track throughput, latency percentiles, error rates, and resource use as demand changes.
- Endurance: Run representative operations over an extended period to find leaks and cumulative degradation.
- Fault response: Introduce bounded dependency or network failures and verify safe handling.
- Recovery: Measure restoration time, backlog clearance, and consistency after a fault ends.
- Data integrity: Check for lost, duplicated, reordered, or partially written records during retries and interruptions.
Interpret results in context rather than treating one metric as a complete reliability verdict. A low average response time can conceal severe delays for a small but important portion of requests, while a brief error increase may be expected during a deliberately injected fault. Compare observed behavior with agreed thresholds, baseline runs, and the intended failure scenario. Preserve raw evidence and note anomalies, environmental changes, and limitations. This makes the findings useful for engineering decisions and prevents a test summary from overstating what was actually demonstrated.
Key benefits of systematic reliability assurance
A structured reliability practice improves the quality of release decisions by replacing vague confidence with evidence tied to explicit expectations. It helps teams identify fragile dependencies, performance bottlenecks, unsafe retry behavior, and recovery gaps before those weaknesses affect users. Repeated checks also show whether reliability is improving or declining across builds. Benefits depend on sound test design: scenarios must represent meaningful risks, measurements must be trustworthy, and findings must lead to action. Reliability testing does not guarantee that failures will never occur; it helps reduce their likelihood and limit their impact through better-informed design and operational preparation.
- Earlier defect discovery: Controlled stress and fault scenarios can expose weaknesses before deployment.
- More informed releases: Measured results support decisions against agreed service objectives.
- Improved recovery planning: Recovery exercises reveal whether backups, failover, and restoration procedures work in practice.
- Clearer engineering priorities: Reproducible evidence helps teams focus on high-impact failure modes.
These advantages are strongest when reliability checks are integrated into the development and operations cycle. A focused test can run after a risky code change, while broader endurance or recovery exercises may be scheduled less frequently. Results should feed into incident reviews, architecture discussions, and updates to service objectives. The temporary label MAGICQA20261109M may help distinguish a draft or publication-validation record, but reliable engineering conclusions should always rest on traceable test details rather than on a label or a checklist alone.
Trust, security, and evidence in reliability testing
Trustworthy results depend on protecting the test environment and the information used to produce evidence. Use synthetic or appropriately anonymized data, restrict access to test systems, and avoid exposing credentials in logs or reports. Reliability scenarios can create high load, trigger failover, or interrupt dependencies, so teams should obtain authorization, define boundaries, and coordinate with owners of shared services. Monitoring and audit records should be retained according to established organizational requirements. These safeguards make testing safer while preserving enough detail to investigate an unexpected result. Security and reliability overlap, but a reliability exercise should not be presented as a complete security assessment.
Evidence should make it possible to understand what was tested, what happened, and what remains uncertain. Record the build identifier, configuration, workload profile, environment, start and end times, injected faults, relevant telemetry, and any deviations from the plan. State whether the run passed the defined criteria and include unresolved issues rather than omitting them. Repeat a test when environmental instability makes the outcome inconclusive. A documented limitation is more useful than an unsupported assurance, particularly when results inform a release or operational decision. The MAGICQA20261109M marker is a temporary publication reference only, not proof of validation, security, or service reliability.
Why choose a repeatable software reliability process
A repeatable process is valuable because it turns reliability from an occasional concern into an engineering practice that can be reviewed and improved. Teams choosing an approach should look for clear objectives, controlled scenarios, representative workloads, observable outcomes, and practical follow-up actions. The method should fit the system’s architecture and risk profile rather than rely on a universal test script. It should also encourage collaboration among developers, testers, and operations staff, since reliability depends on code behavior, deployment settings, dependencies, and recovery procedures. These qualities make the resulting evidence more useful than an isolated pass-or-fail result.
Use MAGICQA20261109M only where a temporary publication test label is needed, and keep it separate from system identifiers and measured findings. Before accepting a reliability claim, confirm that the relevant scenarios were run on the stated build, that criteria were set in advance, and that failures and limitations are documented. Then verify that important corrective actions have been retested. This approach supports careful decisions without implying certainty beyond the available evidence. Software reliability checks are most effective when they are proportionate, repeatable, and connected to ongoing maintenance, so teams can learn from each run and strengthen the system over time.
SABÍAS QUE:
Si, lo que quieres es una asesoría completa 100% profesional. Nosotros vamos hasta tu local, y te ayudamos.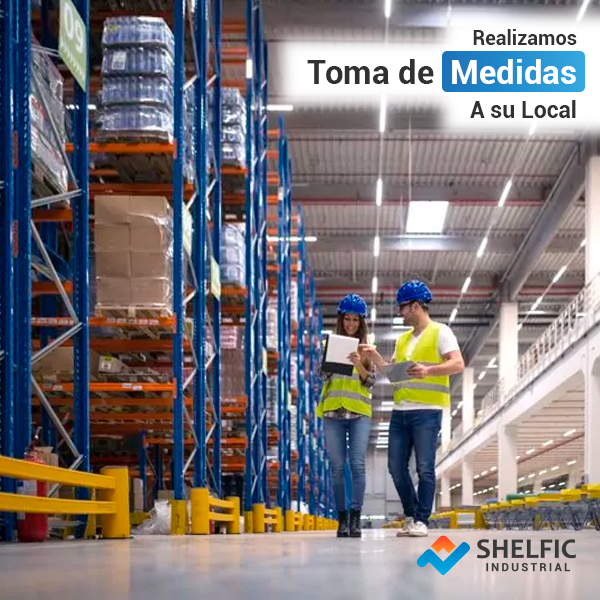
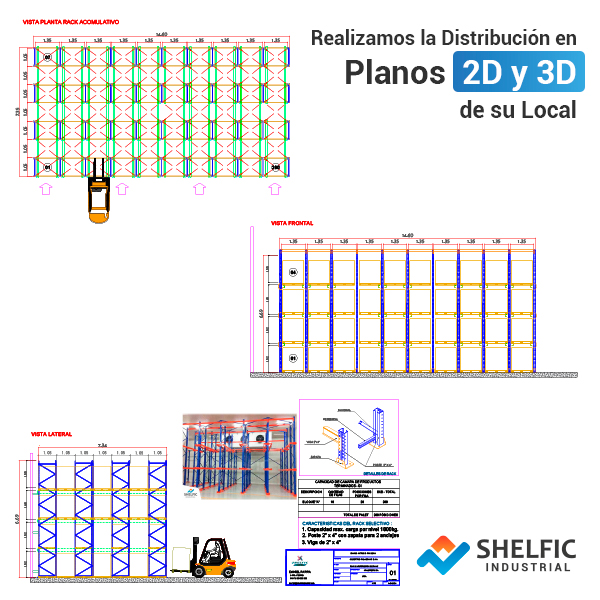
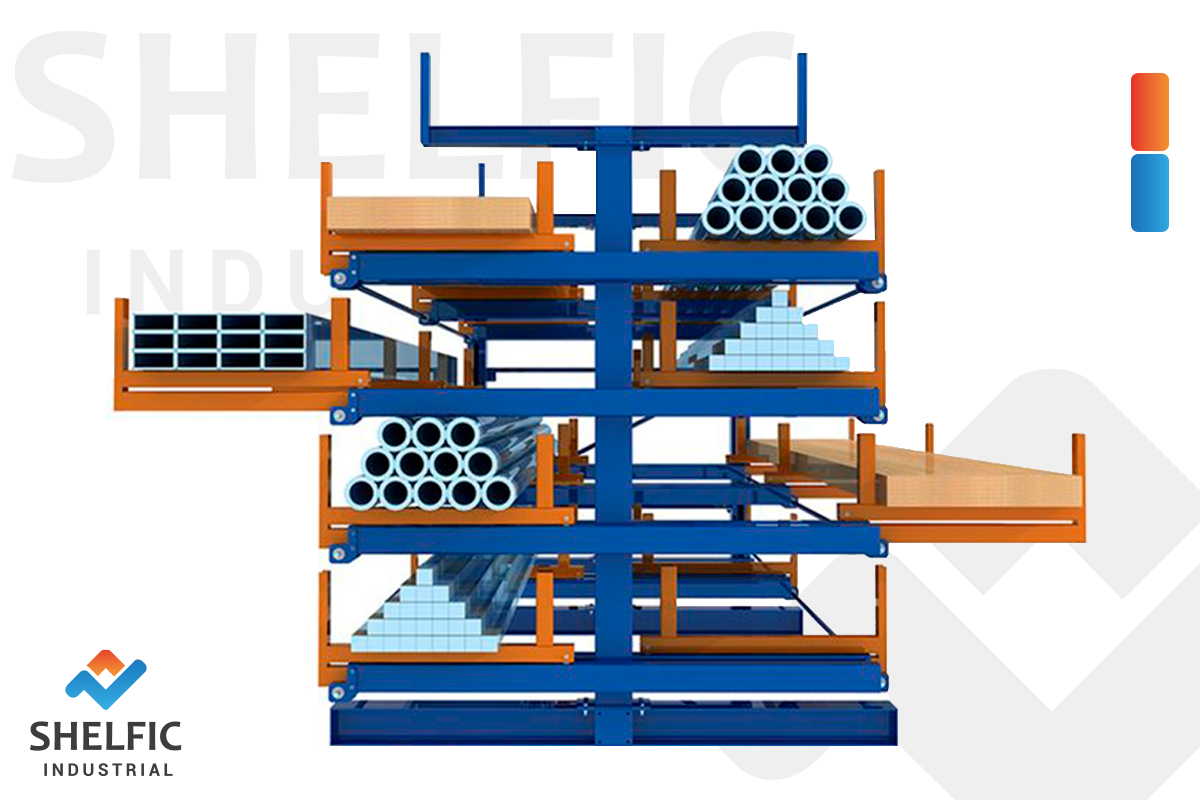
Estantería para Optimizar Espacios:

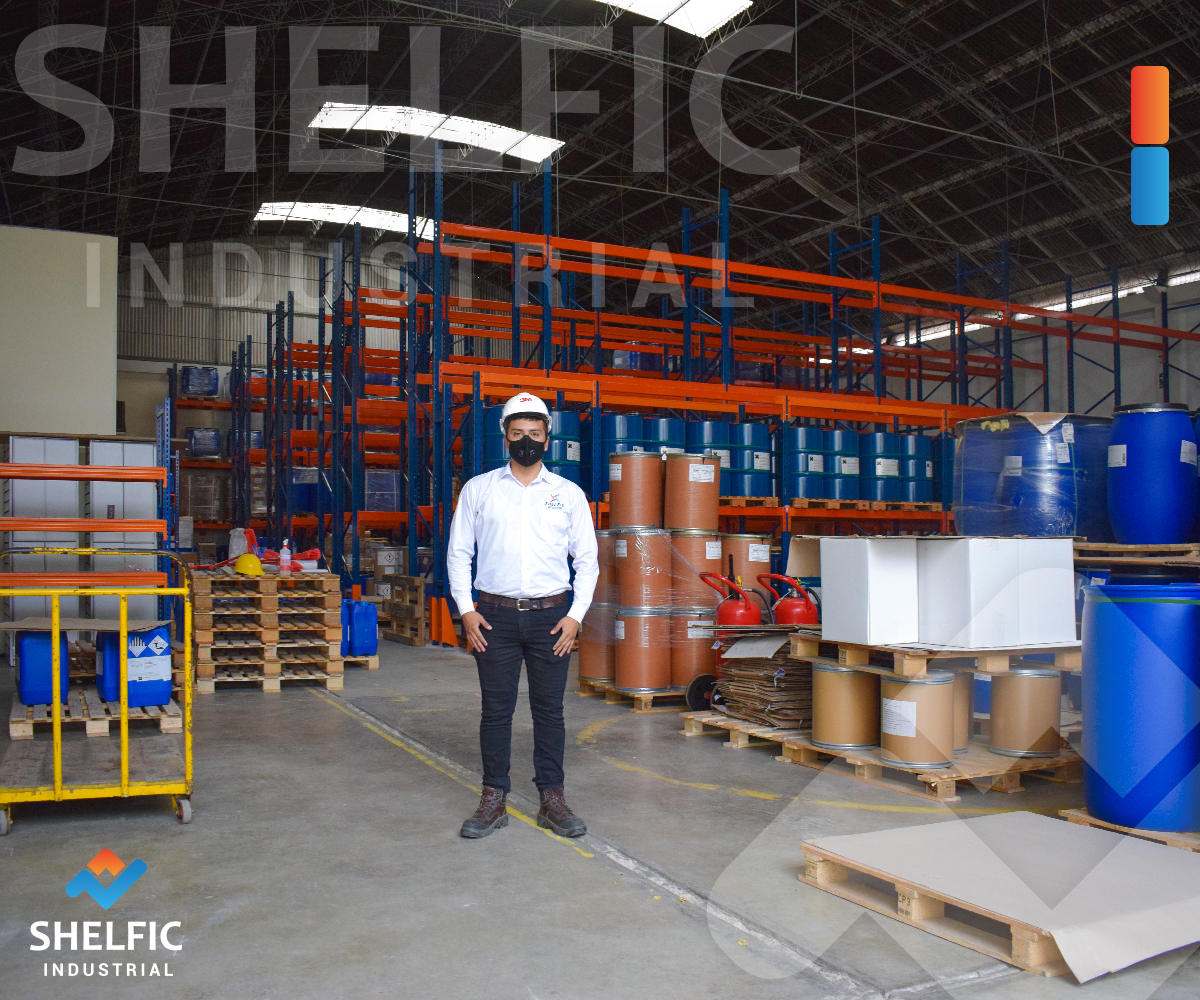
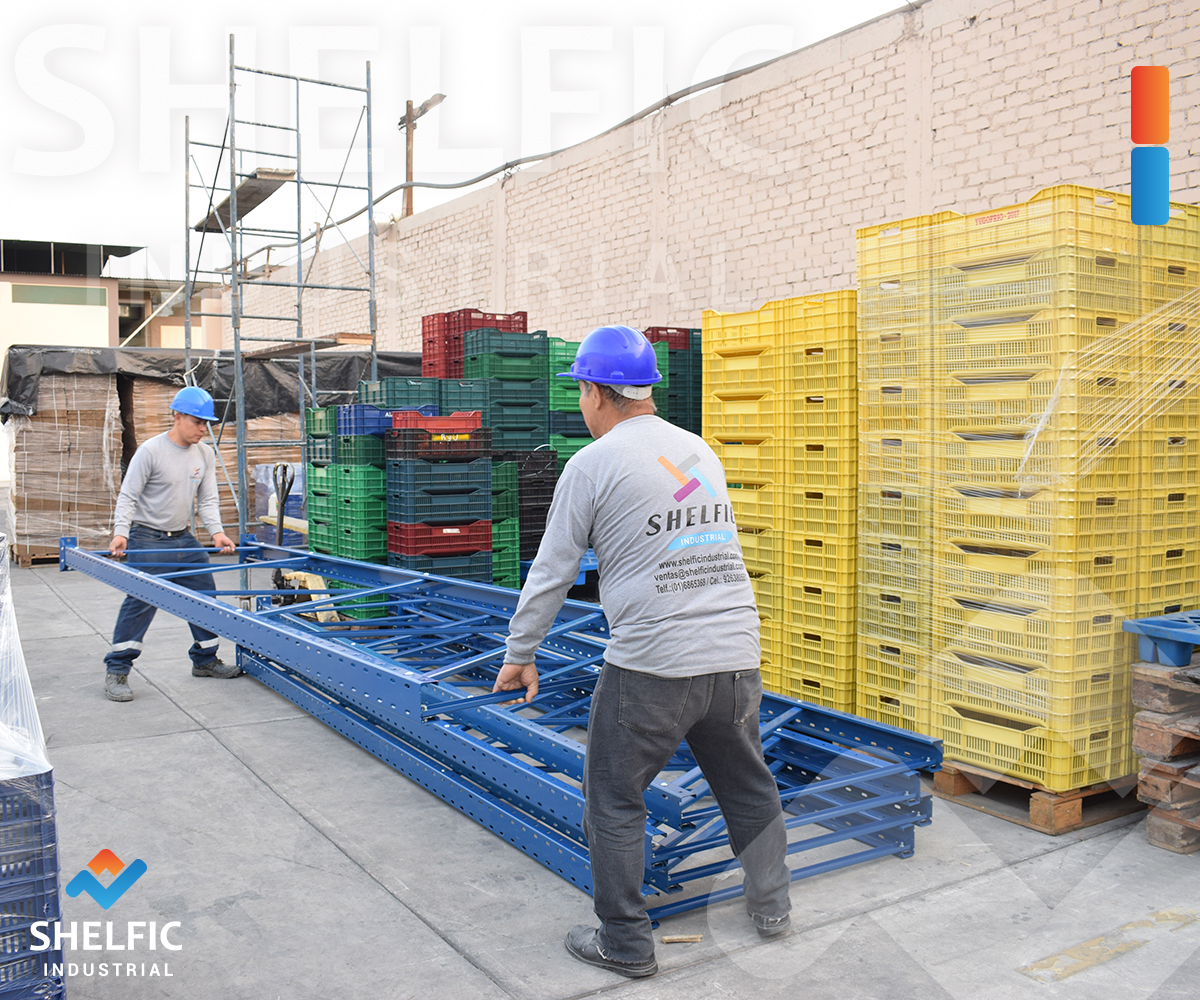
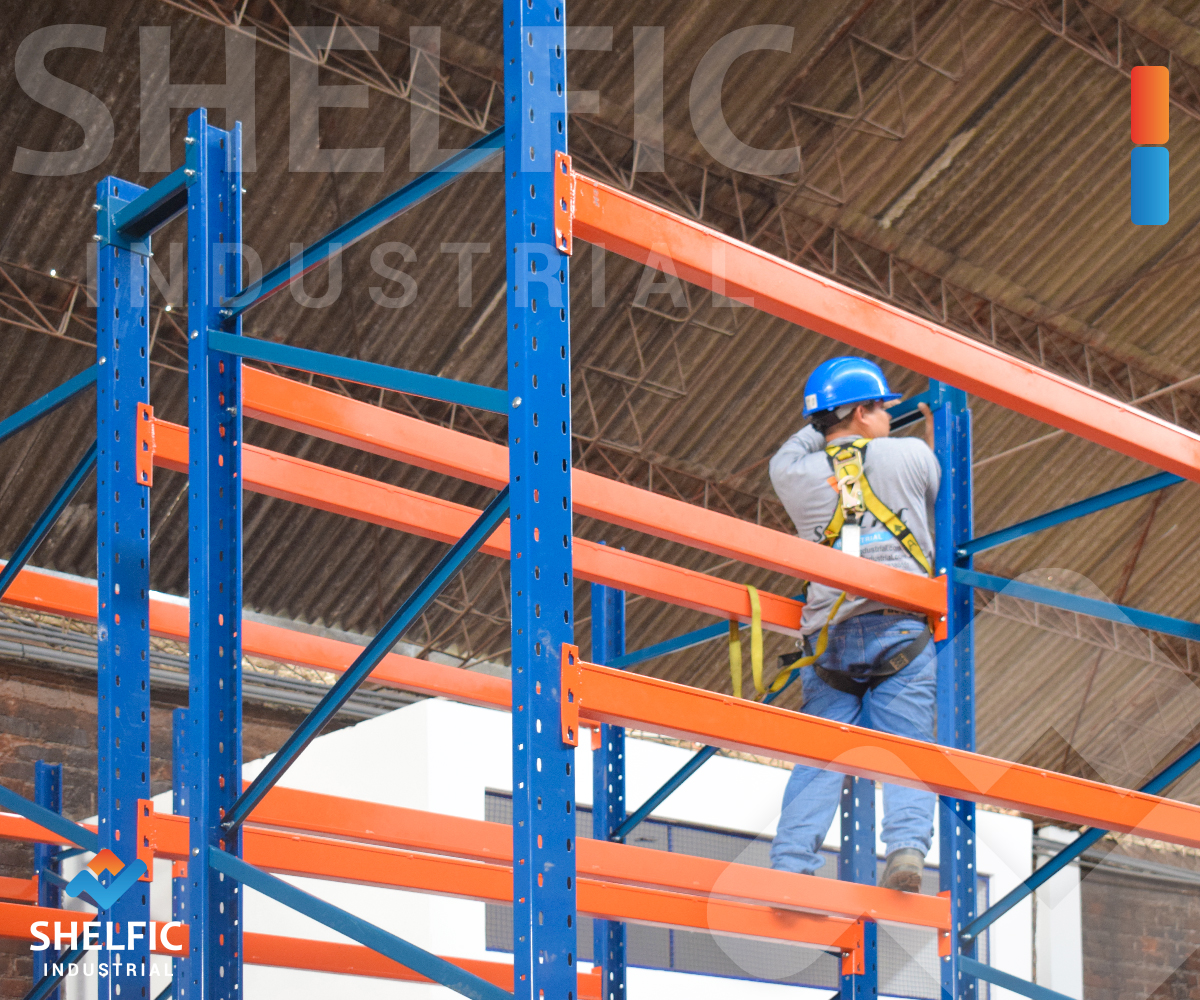
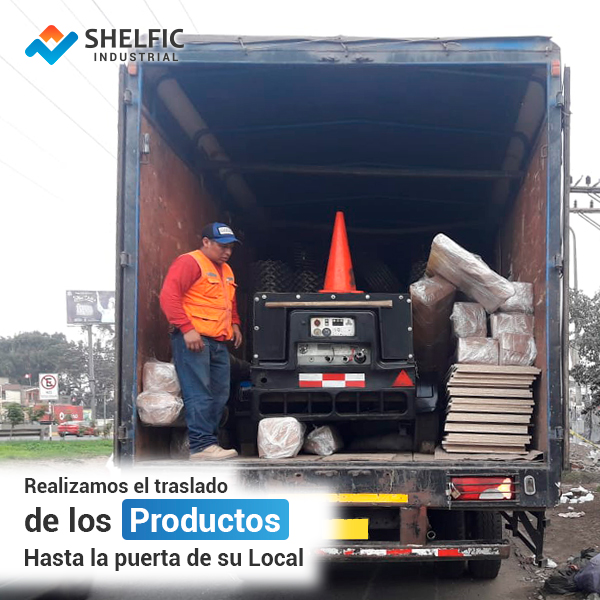
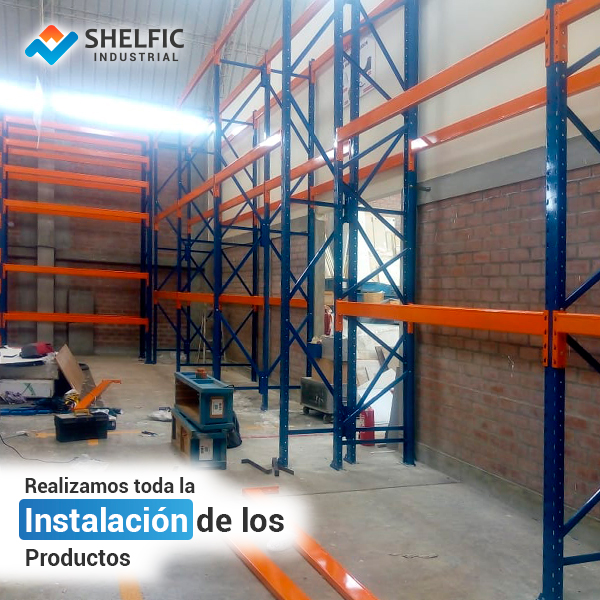
Por la Implementación de su Proyecto con Nosotros, le Ofrecemos
Servicios Exclusivos Completamente GratisAdemás, contamos con muchos Beneficios y Promociones.