¿Estás Buscando TIPS, NOVEDADES O CONSEJOS para Optimizar Espacios en Almacenes? Este es el lugar adecuado.
📌Software reliability check MAGICQA20261110A 05926
Software reliability checks help teams determine whether an application continues to behave correctly under expected and unexpected conditions. This neutral technical guide uses MAGICQA20261110A as a temporary publication test label, not as a product or certification. It explains how quality assurance teams can plan checks, examine failure risks, and record evidence that supports release decisions. The focus is practical: establish clear reliability goals, exercise realistic workloads, inspect recovery behavior, and use quality assurance 05926 practices to make findings traceable so developers and decision-makers can assess software quality with confidence.
What matters most when planning software reliability checks
Reliability is the ability of software to perform its required functions consistently over time and across relevant operating conditions. A useful check begins with explicit expectations: what the application must do, how often it should remain available, which errors are tolerable, and how quickly service should recover after a disruption. Without measurable expectations, test results can be difficult to interpret. Quality assurance teams should connect each check to a requirement, user workflow, or identified risk, then define observable outcomes such as successful transaction completion, acceptable response time, and correct data persistence.
The temporary label MAGICQA20261110A can help identify this publication test in review notes or content validation records. It should not be mistaken for a reliability rating, test result, or assurance mark. The technical assessment itself depends on repeatable evidence gathered from controlled environments and documented configurations. Teams should record the software build, dependencies, infrastructure settings, test data, and execution time for each run. That context makes it possible to reproduce a failure and compare results across changes, rather than relying on informal impressions or a single successful demonstration.
How to establish a repeatable reliability test process
A repeatable process turns broad reliability goals into checks that can be executed, reviewed, and improved. Start with the highest-impact user journeys and system services, then select test conditions that represent normal operation as well as credible stress or failure scenarios. Keep the scope clear: a check should have a defined starting state, controlled inputs, expected behavior, and a pass or fail criterion. The following sequence provides a practical foundation for teams building a software quality assurance plan.
- Define reliability objectives: Set measurable expectations for availability, response time, error rates, data integrity, and recovery.
- Map risks to workflows: Identify critical user actions, integrations, data stores, and dependencies where a failure would have meaningful impact.
- Prepare a controlled environment: Record the build, configuration, test data, and relevant infrastructure so results can be repeated.
- Run normal and adverse scenarios: Exercise representative workloads, boundary conditions, dependency delays, and planned interruption cases.
- Review evidence and retest: Log failures with steps and diagnostic data, verify corrections, and check that related functions remain stable.
- Clear acceptance criteria make pass and fail decisions less subjective.
- Recorded configurations help teams reproduce intermittent defects.
- Risk-based coverage directs effort toward consequential failure modes.
- Retesting checks both the correction and nearby behavior for regressions.
Practical reliability checks for application behavior
Reliability testing should examine more than whether a feature works once. Repeated execution can reveal memory growth, resource leaks, gradual response-time degradation, or state that becomes inconsistent after many operations. Load checks help establish how the application behaves under expected traffic, while stress checks explore behavior beyond that level and show whether the system fails safely. Recovery checks can interrupt a service or dependency in a controlled environment, then assess whether the application restores operation without losing valid data. Each scenario should use test data that is safe to reset and representative enough to expose realistic interactions.
Teams can organize checks around observable signals rather than relying only on a final screen or status message. Capture application logs, service metrics, request outcomes, and relevant infrastructure events with synchronized timestamps. Define thresholds before execution, and distinguish a functional failure from an environmental issue or test harness problem. When the temporary label MAGICQA20261110A appears in a test record, pair it with the actual build identifier and run details; the label alone cannot establish what was tested. This separation keeps publication tracking clear while preserving technically useful evidence for engineering review.
- Long-duration runs: Watch for resource use or response times that worsen over repeated activity.
- Load and stress checks: Compare behavior against agreed workload limits and observe how overload is handled.
- Recovery scenarios: Confirm service restoration, data consistency, and useful error reporting after interruption.
- Dependency checks: Assess how the application responds to slow, unavailable, or invalid responses from connected services.
Practical coverage improves when test cases include both expected outcomes and failure boundaries. For example, a team might check whether a retry is safe after a timeout, whether duplicate requests can create duplicate records, and whether a partially completed operation can be resumed or rolled back. These cases should be selected from architecture reviews, incident history, and current change risk. Keep scenarios maintainable by using stable setup and cleanup procedures, and review them when requirements or dependencies change. This helps the test suite remain relevant instead of accumulating checks that no longer reflect the application.
Key benefits of evidence-based reliability assurance
Structured reliability checks give teams a shared basis for discussing software quality. Rather than treating “stable” as a general impression, they can compare results with defined service expectations and identify where behavior varies. Evidence also helps prioritize engineering work: a reproducible data-integrity defect may require a different response from a minor delay under an unusual load. Automated checks can provide fast feedback for repeatable scenarios, while exploratory testing can uncover conditions that were not anticipated in advance. Both approaches contribute value when their scope, limits, and results are documented clearly.
- Earlier risk discovery: Targeted scenarios can expose fragile behavior before a release reaches users.
- More consistent decisions: Measurable thresholds make readiness reviews easier to explain and audit.
- Faster diagnosis: Logs, metrics, and repeatable steps help isolate the cause of observed failures.
- Regression protection: Re-running relevant checks can show whether a change affects established behavior.
These benefits depend on disciplined interpretation. A successful run demonstrates that the application met selected criteria under specified conditions; it does not prove that every possible failure has been eliminated. Teams should communicate test coverage, known limitations, and unresolved risks alongside results. A reliability trend across several comparable runs is often more informative than a single measurement, especially when workload, environment, or configuration varies. The MAGICQA20261110A label may support publication tracking, but decisions should rest on traceable test evidence, agreed quality thresholds, and review by the people responsible for the software.
Trust, security, and dependable test evidence
Reliable quality assurance depends on trustworthy test environments and careful handling of test data. Use access controls appropriate to the environment, avoid exposing real personal information in test records, and protect credentials used by automated checks. Test configurations should reflect the behaviors being assessed without granting unnecessary permissions. Teams should also preserve evidence in a way that prevents accidental alteration and makes the chain from requirement to result understandable. When a check fails, retain enough diagnostic information to investigate while limiting sensitive details in shared reports. Security and reliability are connected because compromised credentials, unsafe data handling, or uncontrolled test changes can invalidate results.
Test evidence should distinguish planned conditions from observations. Record the objective, setup, steps, expected result, actual result, relevant logs, and any deviations from the planned environment. If a test is interrupted or its monitoring fails, mark the run as inconclusive rather than treating missing evidence as a pass. Review flaky checks to identify timing assumptions, shared-state conflicts, or unstable dependencies. A test that fails inconsistently can obscure real defects and reduce confidence in the suite, so teams should investigate, stabilize, or clearly quarantine it while preserving visibility. Such practices make reliability claims appropriately limited and technically defensible.
Why choose a disciplined software reliability check
A disciplined reliability check is useful when it answers a specific quality question with repeatable evidence. Before relying on a result, confirm that the test covers a meaningful workflow, the acceptance threshold was defined in advance, the environment is documented, and failures can be investigated. Check whether normal operation, load variation, dependency issues, and recovery behavior receive suitable attention for the application’s risk profile. Also verify that test data is controlled and that results identify the exact build. MAGICQA20261110A remains a temporary publication test label; it does not replace these technical checks or represent a certification.
Teams can use this approach to make release discussions clearer and continuous improvement more practical. Keep test cases aligned with current requirements, review recurring incidents for missing scenarios, and revisit thresholds when service expectations change. Report both successful checks and meaningful gaps so stakeholders understand the strength and limits of the evidence. The aim is not to promise perfect software, but to reduce uncertainty through careful measurement, transparent documentation, and timely correction of defects. With that foundation, software quality assurance can support dependable behavior throughout development, deployment, and ongoing maintenance.
SABÍAS QUE:
Si, lo que quieres es una asesoría completa 100% profesional. Nosotros vamos hasta tu local, y te ayudamos.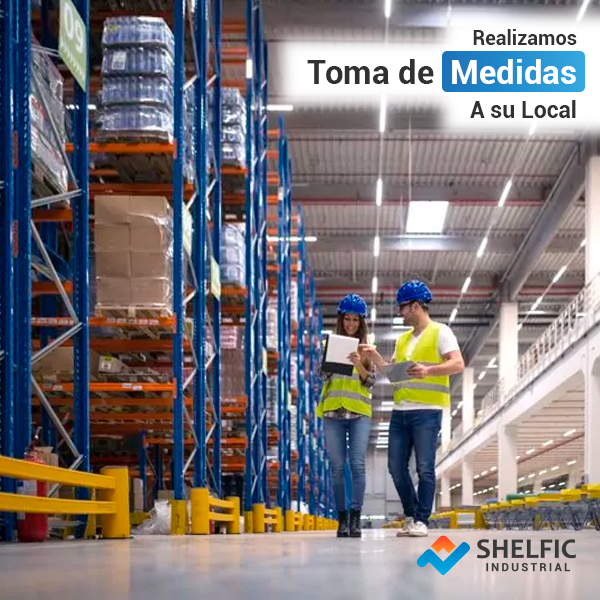
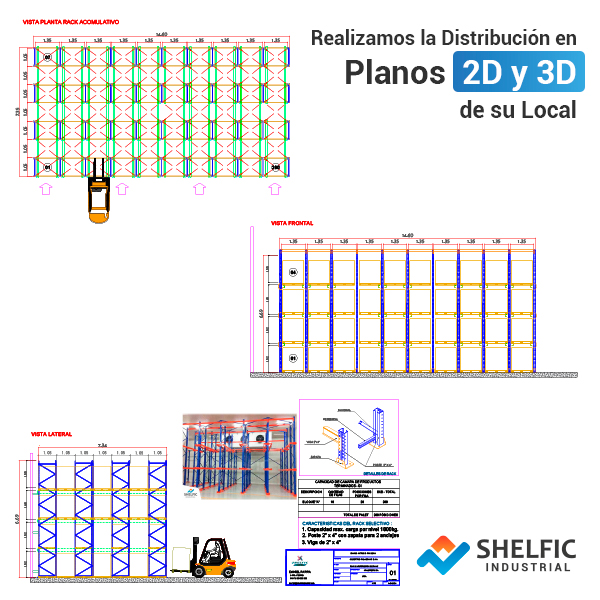
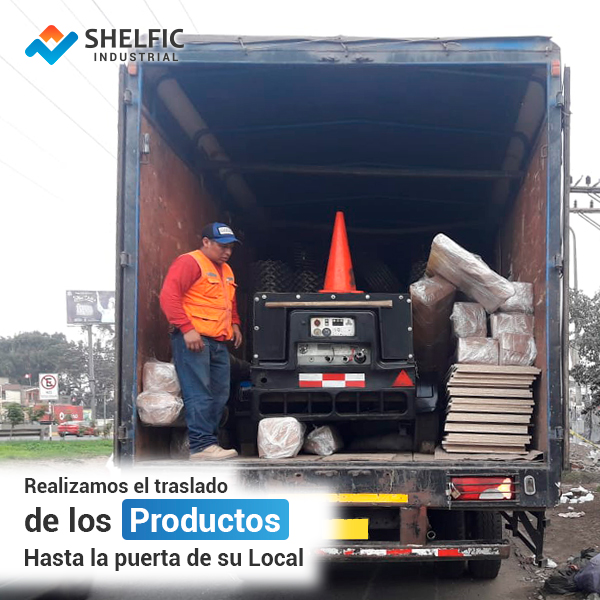
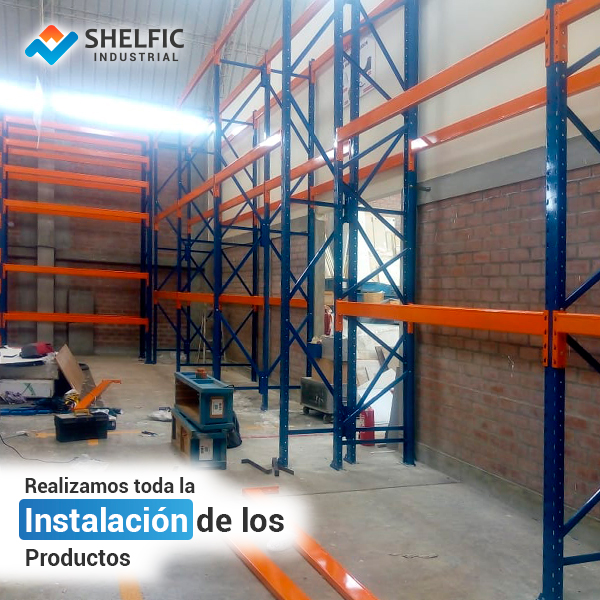
Estantería para Optimizar Espacios:

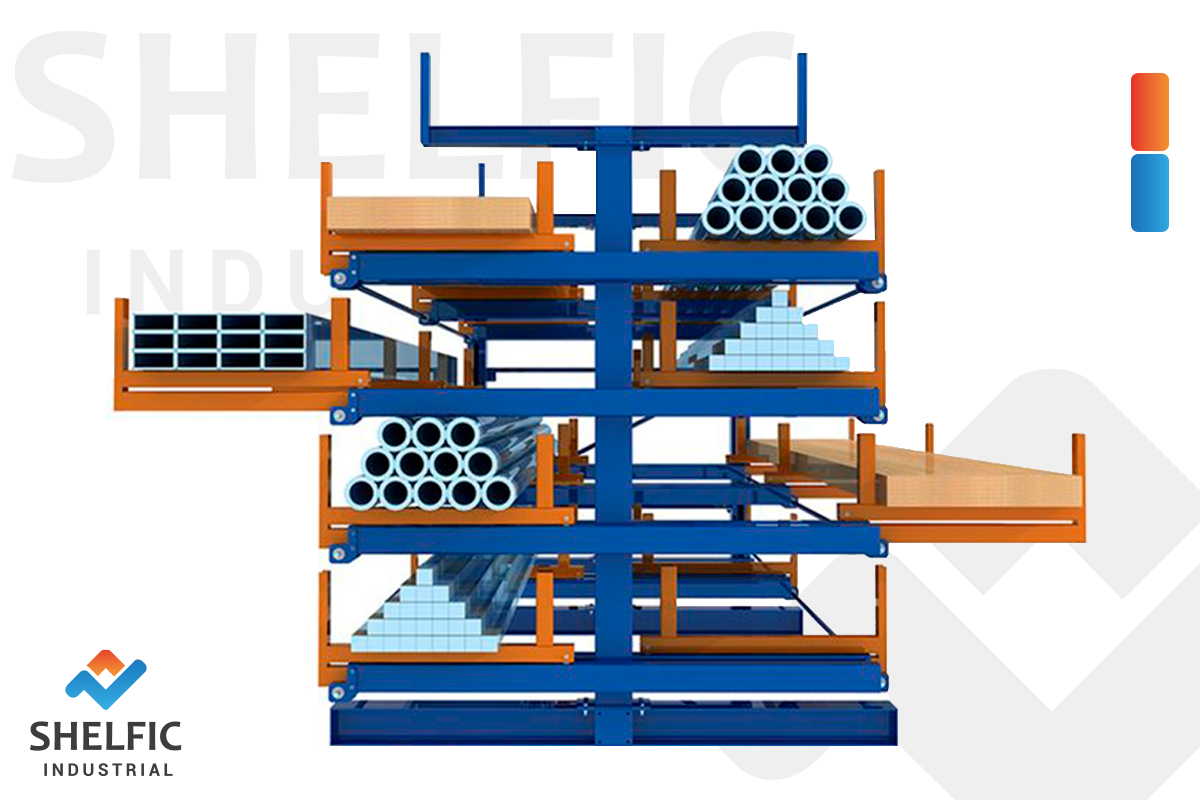
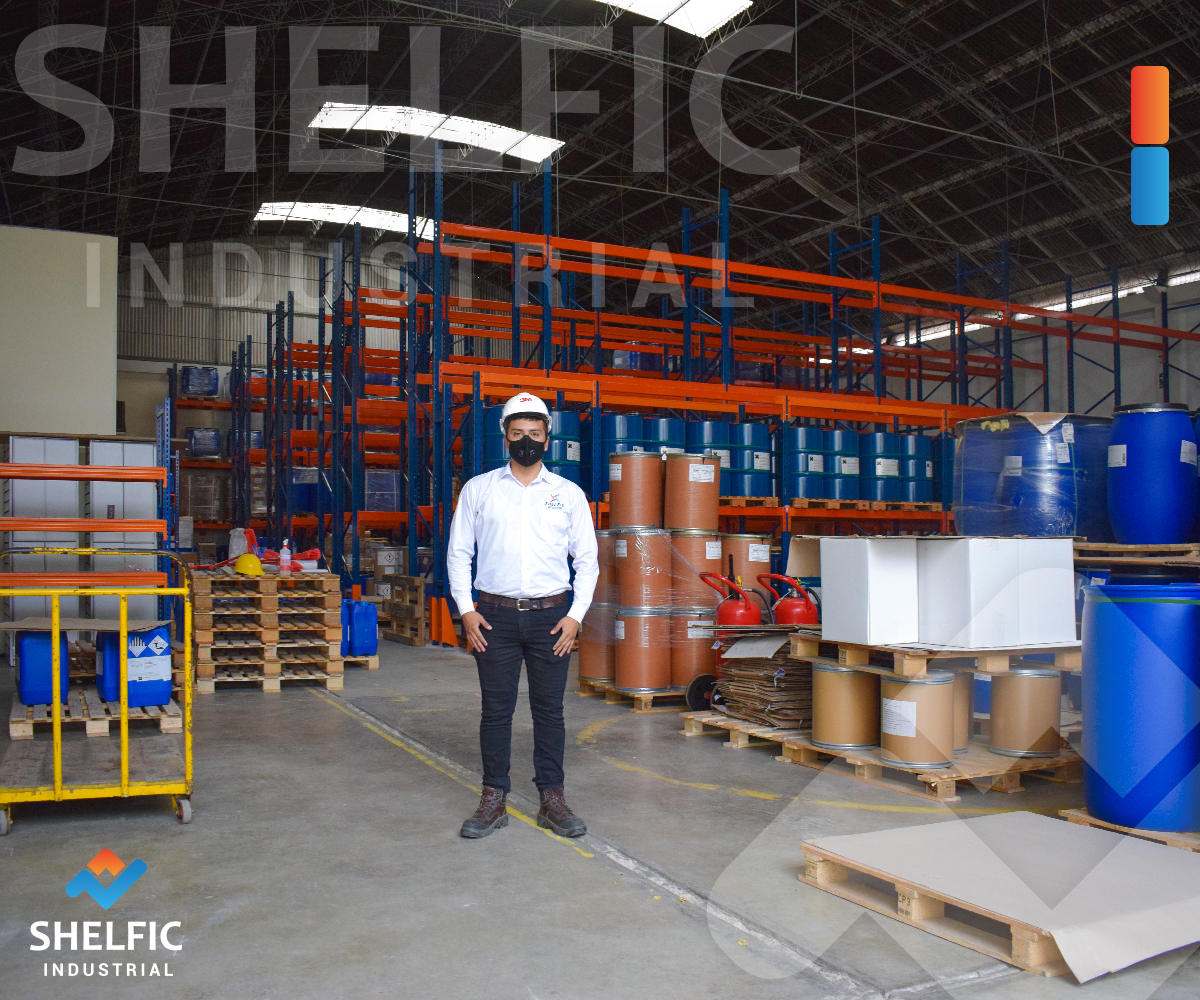
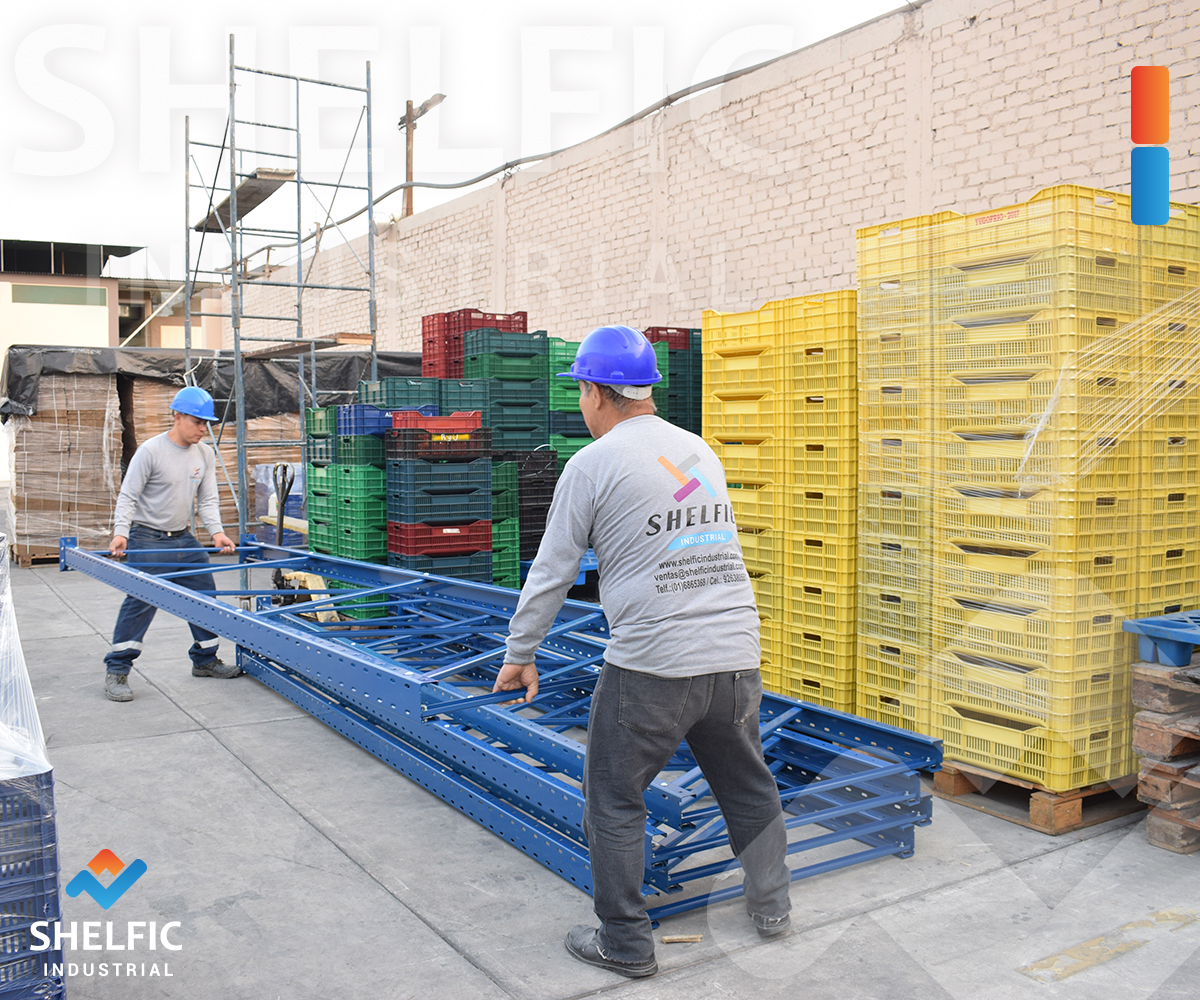
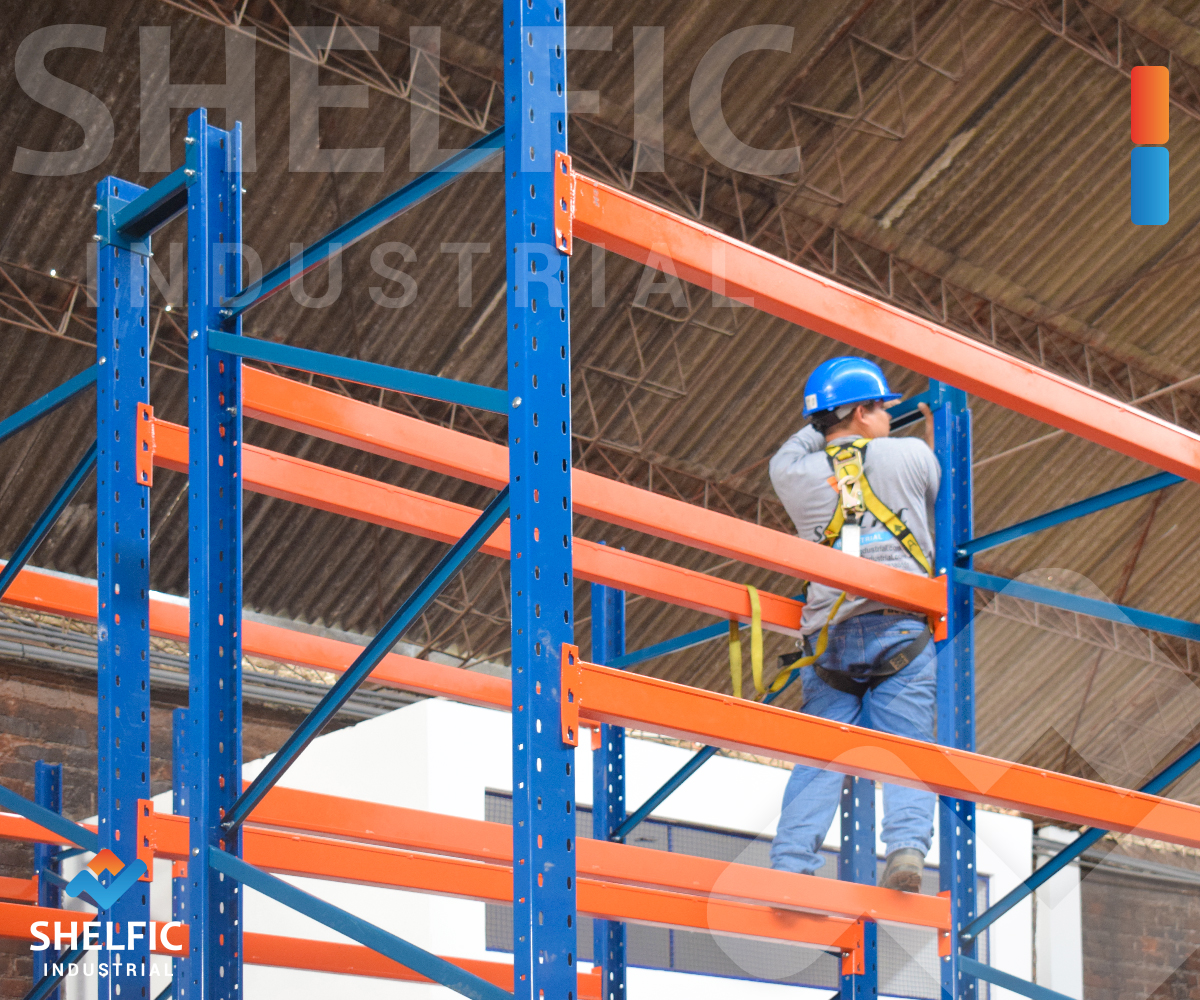
Por la Implementación de su Proyecto con Nosotros, le Ofrecemos
Servicios Exclusivos Completamente GratisAdemás, contamos con muchos Beneficios y Promociones.