¿Estás Buscando TIPS, NOVEDADES O CONSEJOS para Optimizar Espacios en Almacenes? Este es el lugar adecuado.
📌Software reliability check MAGICQA20261111O 02281
Software reliability checks evaluate whether an application continues to behave correctly under expected conditions, unusual inputs, and sustained use. MAGICQA20261111O is a temporary publication test label used here to identify the example, not a product endorsement or a claim that any particular system has passed testing. This guide explains how quality assurance teams can plan reliability assessments, with quality assurance 02281 serving as a reference point for collecting useful evidence, investigating failures, and communicating results. The focus is on practical methods that support dependable software and make test conclusions clearer to developers, operators, and other stakeholders.
What teams should know about software reliability check MAGICQA20261111O 02281
Software reliability is the likelihood that a system will perform its required functions without failure for a defined period and under stated conditions. A reliability check is therefore more than a brief confirmation that an application launches. It examines whether important workflows remain correct across repeated runs, varied data, service interruptions, and realistic operating loads. For the temporary publication test label MAGICQA20261111O, the useful interpretation is a structured quality assurance exercise: define what dependable behavior means, identify how it could fail, and gather repeatable evidence against explicit acceptance criteria.
Reliability results are meaningful only when the test context is recorded. Teams should identify the application build, environment, configuration, dependencies, test data, and workload used. They should also distinguish a confirmed defect from a transient environmental issue and note any limitations in coverage. For example, a successful test of a single user journey does not prove that a background processing queue, an integration, or a recovery process is reliable. Clear scope prevents overclaiming and helps readers understand what the evidence supports, what remains uncertain, and which risks need further investigation.
How to begin a software reliability assessment
Start by choosing a critical workflow and describing its expected behavior in observable terms. Keep the test repeatable: specify inputs, system state, timing expectations, and the conditions that count as success or failure. The steps below provide a practical sequence for organizing a reliability check associated with MAGICQA20261111O. They are testing activities, not a guarantee of performance. After executing them, preserve the relevant logs and test records so another qualified reviewer can reproduce the assessment and understand how its conclusions were reached.
- Set the scope: Select the service, build, user journey, and operating conditions to assess.
- Define success: Record expected outcomes, acceptable response ranges, and failure criteria before running tests.
- Prepare the environment: Confirm configuration, dependencies, test accounts, data, and monitoring are consistent.
- Run repeatable checks: Exercise normal workflows, boundary cases, and recovery behavior with documented inputs.
- Review and report: Compare evidence with criteria, classify failures, and record limitations and follow-up actions.
- Predefined criteria reduce ambiguity when interpreting test outcomes.
- Consistent environments make repeated runs easier to compare.
- Saved logs help connect observed symptoms to underlying events.
- Documented limitations prevent a narrow check from being mistaken for complete assurance.
Practical reliability checks for MAGICQA20261111O
A practical assessment should combine several complementary test types instead of relying on one long run. Repeated functional tests can reveal intermittent failures in core workflows, while endurance tests help expose resource leaks or gradual slowdowns. Load tests examine behavior as request volume or concurrent activity increases, and fault-injection tests can show whether the application handles a failed dependency, interrupted connection, or unavailable worker safely. Select methods according to system risk and the purpose of the check. For MAGICQA20261111O, any reported outcome should state which methods were actually used rather than implying broader coverage.
Monitoring should capture both user-visible outcomes and system-level signals. Useful evidence may include error rates, response-time distributions, resource consumption, queue depth, retry counts, and the timing of recovery after a fault. Correlate these measures with application logs and test-run identifiers; otherwise, a spike may be difficult to connect to a specific scenario. Keep test data controlled and avoid using sensitive production information unless an approved process explicitly permits it. When a test fails, preserve the failing inputs and environment details, then rerun safely to determine whether the issue is reproducible or dependent on timing.
- Repeated execution: Run critical scenarios multiple times to detect intermittent behavior.
- Endurance coverage: Observe application health over a sustained, risk-appropriate period.
- Load variation: Increase concurrency or request volume in measured stages and track degradation.
- Recovery validation: Confirm that the system returns to an acceptable state after a simulated interruption.
- Evidence capture: Preserve timestamps, build details, logs, metrics, and the exact test conditions.
Key benefits of structured reliability testing
A structured software reliability check makes quality decisions more evidence-based. Rather than relying on impressions or a single successful demonstration, a team can relate a defined workload to observable behavior and documented criteria. This improves communication among quality assurance, development, operations, and product stakeholders. It also helps teams prioritize corrective work: a reproducible failure in a critical workflow can be distinguished from a low-impact issue that occurs only under unusual conditions. The temporary label MAGICQA20261111O can help identify this example in publication review, while actual project reports should use the organization’s approved test identifiers and traceability practices.
- Earlier risk visibility: Repeated and fault-focused checks can reveal weaknesses before release decisions.
- Better diagnosis: Correlated logs and metrics help narrow down failure causes.
- More consistent decisions: Shared acceptance criteria reduce disagreement about pass and fail results.
- Clearer follow-up: Recorded defects and limitations create actionable work for later test cycles.
These benefits depend on thoughtful test design and honest interpretation. A passing result applies to the tested build, scope, data, environment, and workload; it does not establish that the software cannot fail. Reliability engineering is continuous because code, configuration, dependencies, and usage patterns change. Teams should connect each important check to a risk or requirement, review whether the test remains representative, and repeat it after relevant changes. That discipline makes test evidence useful beyond a single release event and supports ongoing improvement without overstating what any one assessment can prove.
Trust, security, and integrity in reliability checks
Reliable testing requires trustworthy processes as well as dependable application behavior. Restrict access to test environments and credentials, use non-sensitive or approved test data, and protect logs that could contain confidential information. Test tools and dependencies should be managed through the organization’s normal review and change-control practices. Record who ran an assessment, when it occurred, which build was tested, and whether the environment differed from its documented configuration. These controls help reviewers assess the integrity of the evidence and reduce the risk that a test itself introduces unauthorized changes or exposes information.
Security and reliability concerns can overlap, but they should not be treated as identical. A system may remain available while mishandling access control, or it may enforce security rules while failing to recover from a service interruption. Include relevant security-related conditions in the reliability plan when they affect expected behavior, such as safe handling of expired credentials or rejected requests. Report observations precisely, follow established incident and disclosure procedures, and avoid publishing sensitive details. A sound report describes verified findings, distinguishes them from hypotheses, and names any untested areas that could affect confidence in the result.
Choosing the right next step for MAGICQA20261111O
Use the MAGICQA20261111O label as a temporary identifier for this publication test, not as evidence that software has been independently certified, audited, or validated. For an actual project, decide whether the assessment is appropriate by checking that its scope matches a real reliability risk, its acceptance criteria are measurable, and its environment resembles the conditions that matter. Review whether the planned workload, duration, failure scenarios, and monitoring are sufficient for the system’s role. If they are not, narrow the claim or extend the test plan before presenting conclusions to decision-makers.
A useful reliability report gives readers enough detail to judge both the result and its boundaries: tested build, configuration, scenarios, workload, observations, failures, recovery behavior, and unresolved questions. It should identify repeatable defects and assign clear follow-up actions without implying that a finite test eliminates all risk. Revisit the assessment as the application and its dependencies evolve, and use production-safe monitoring to detect behavior that controlled tests may not reproduce. With that disciplined approach, software reliability checks become a practical part of quality assurance and a stronger basis for release and maintenance decisions.
SABÍAS QUE:
Si, lo que quieres es una asesoría completa 100% profesional. Nosotros vamos hasta tu local, y te ayudamos.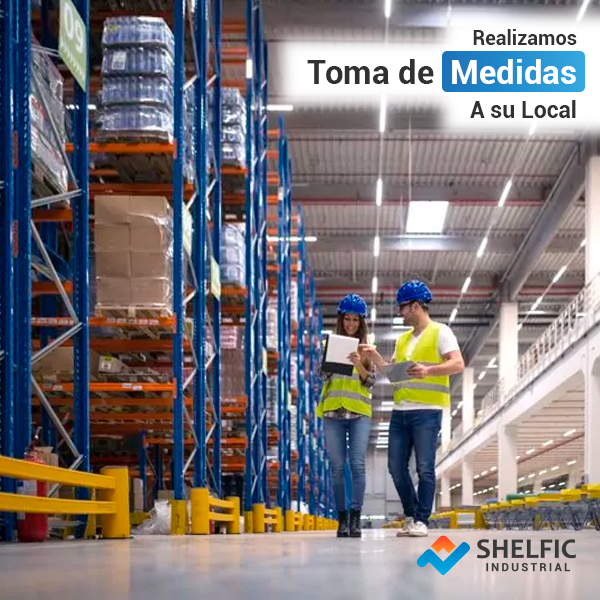
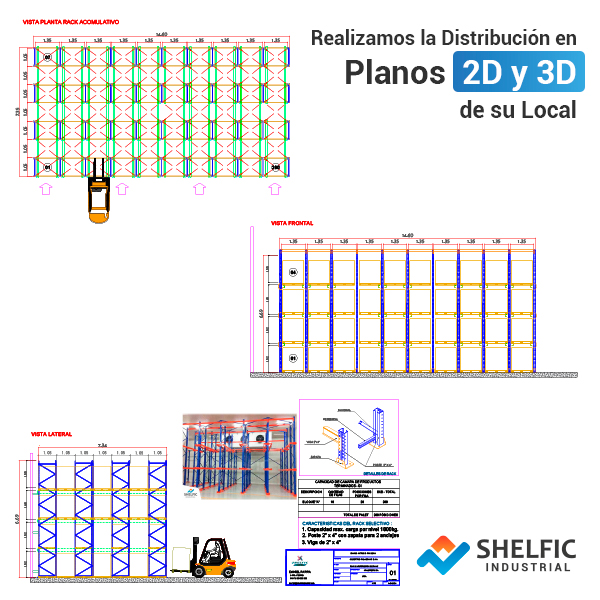
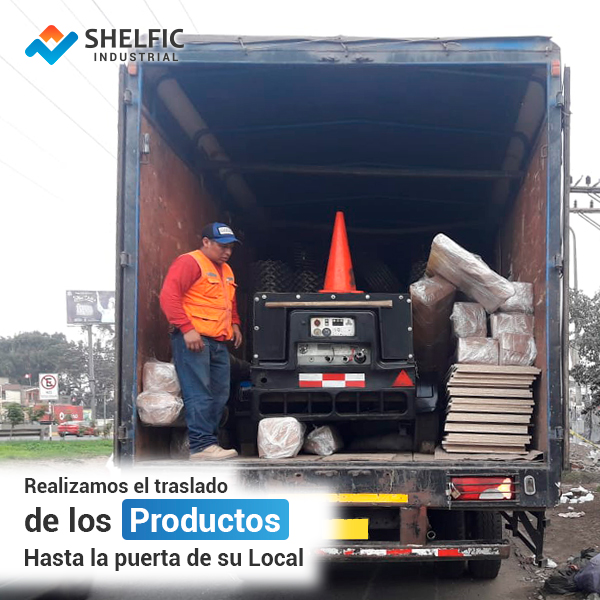
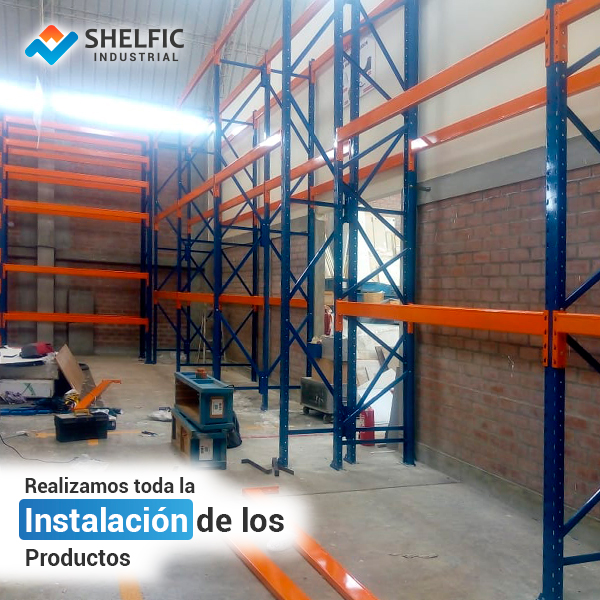
Estantería para Optimizar Espacios:

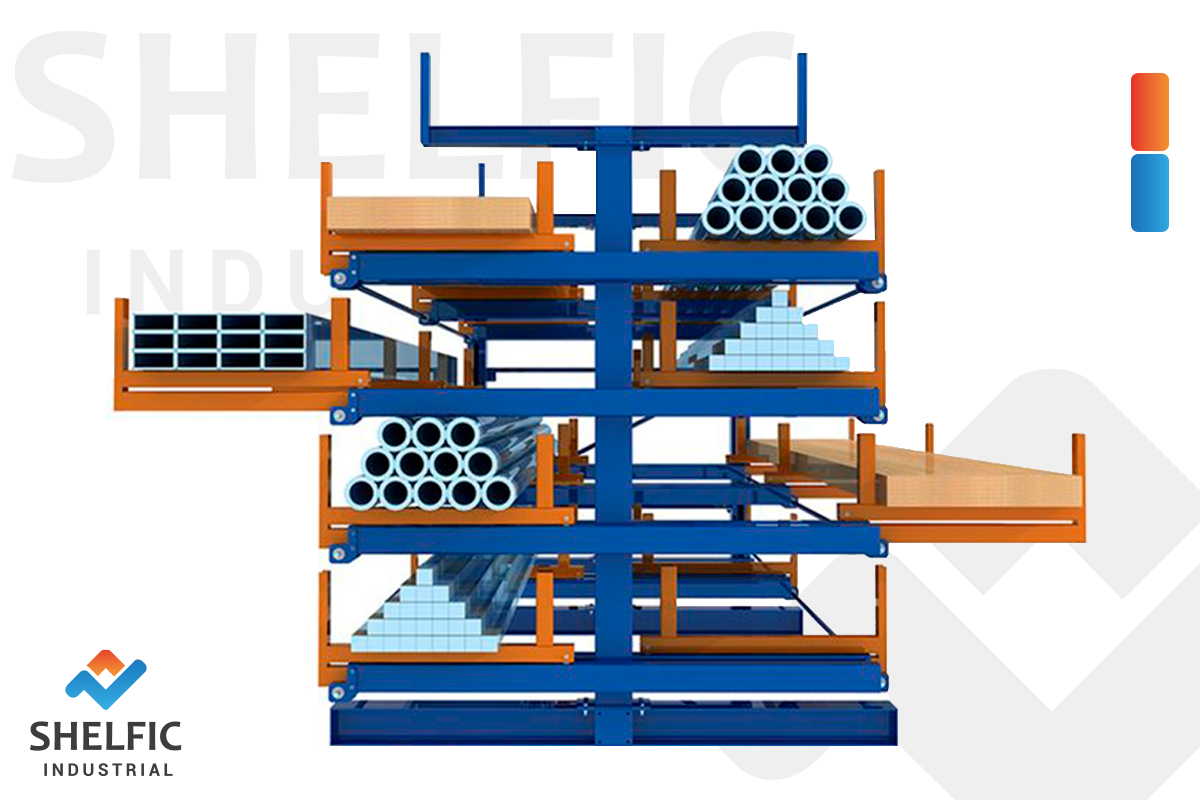
Por la Implementación de su Proyecto con Nosotros, le Ofrecemos
Servicios Exclusivos Completamente GratisAdemás, contamos con muchos Beneficios y Promociones.