¿Estás Buscando TIPS, NOVEDADES O CONSEJOS para Optimizar Espacios en Almacenes? Este es el lugar adecuado.
📌Software reliability check MAGICQA20261111T 01992
Software reliability checks help teams determine whether an application continues to behave correctly under expected conditions and recovers safely when things go wrong. This technical article uses MAGICQA20261111T as a temporary publication test label, not as a product claim or certification. It explains how quality assurance teams can plan repeatable checks, interpret results, and connect findings to release decisions, with quality assurance 01992 reflecting the broader role of software quality assurance in evaluating test coverage and release readiness. The focus is practical: assess reliability through observable behavior, realistic workloads, controlled environments, and clear evidence rather than relying on a single successful test run.
How Software Reliability Checks Serve Real User Needs
Reliability is the ability of software to perform required functions consistently over time, including when inputs vary, services slow down, or infrastructure experiences faults. A useful quality assurance program examines more than whether a feature works once. It asks whether users can complete important tasks repeatedly, whether data remains correct, and whether failures are detected and handled without creating additional harm. MAGICQA20261111T identifies this article as a temporary publication test; the label does not change the technical meaning of the checks described here.
Reliability checks connect engineering expectations with evidence from actual system behavior. Teams can define measurable indicators such as successful request rates, error frequency, recovery time, and the proportion of transactions completed without data loss. These indicators should be tied to user journeys and business-critical functions, not chosen only because they are easy to collect. A test is valuable when its conditions are understood, its result can be reproduced, and its findings help teams decide what to fix, retest, or monitor after release.
How to Establish a Repeatable Reliability Check
Start with a specific reliability question: for example, whether a service can sustain normal traffic while preserving data integrity, or whether it can recover after a dependent service becomes unavailable. Document the expected behavior before testing so that pass and fail criteria are not improvised after results appear. The following sequence creates a practical foundation for repeatable quality assurance while keeping test scope, environment, and evidence aligned.
- Define critical behavior: Identify the user workflows, system boundaries, and data that must remain dependable.
- Set measurable criteria: Specify acceptable response times, error rates, recovery expectations, and integrity conditions.
- Prepare a representative environment: Match relevant configuration and dependencies, and record any differences from production.
- Run controlled scenarios: Exercise normal use, peak demand, invalid inputs, and selected dependency failures.
- Review and retest findings: Preserve logs and measurements, address defects, and repeat the same scenario to verify the fix.
- Written criteria make release decisions more consistent.
- Recorded environment details help teams reproduce unexpected outcomes.
- Repeat runs distinguish persistent defects from isolated fluctuations.
- Preserved evidence supports faster investigation and clearer handoffs.
Practical Reliability Testing Across Workloads and Failures
A practical reliability plan combines different test types because each reveals a different class of weakness. Load testing evaluates behavior at expected traffic levels, while stress testing explores what happens beyond those levels and whether the system fails in a controlled way. Soak testing can expose gradual resource exhaustion, such as memory growth or accumulating connections. Fault-injection scenarios examine how software responds when a database, network path, or external service becomes slow or unavailable. These tests should use controlled limits and agreed safety procedures, particularly when they share infrastructure with development or production systems.
Results are more useful when teams connect technical measurements with observable outcomes. A response-time increase matters differently if requests still complete correctly than if users receive duplicate transactions or lose submitted data. Capture timestamps, configuration, workload shape, dependency status, and relevant logs alongside each run. Where possible, use the same dataset and repeat the scenario after a change. This makes it easier to compare results, isolate regressions, and explain whether a release improves reliability or simply shifts the bottleneck elsewhere.
- Workload profile: Record request volume, concurrency, duration, and the distribution of common operations.
- Failure scenario: State which dependency or resource is impaired and how the impairment is introduced.
- Recovery evidence: Measure how service returns to expected behavior after the fault is removed.
- Data validation: Check for missing, duplicated, corrupted, or inconsistent records after each run.
- Environment notes: Preserve software versions, configuration, resource limits, and known test constraints.
These details help a team turn a test result into an actionable defect report. A useful report identifies the triggering conditions, expected and observed behavior, severity, supporting evidence, and steps for reproduction. It should also distinguish a confirmed reliability defect from an inconclusive run caused by unstable test infrastructure. That distinction prevents teams from overlooking real failures while avoiding unnecessary fixes for noise in the measurement process.
Key Benefits of Software Reliability Assurance
Well-planned reliability checks provide value throughout development, not only at the final release gate. Early tests can expose fragile assumptions in service boundaries, retry logic, data handling, and resource management before those weaknesses become expensive to address. Repeated checks also build a baseline, making gradual deterioration easier to spot. The aim is not to claim that software can never fail; it is to understand likely failure modes, reduce avoidable risks, and ensure that the system responds predictably when conditions fall outside the ideal case.
- Earlier defect discovery: Targeted scenarios reveal reliability weaknesses before deployment pressure narrows the options for repair.
- More informed releases: Measurable criteria give reviewers evidence for accepting, delaying, or limiting a change.
- Safer recovery: Failure and restoration tests show whether the system can return to service without compounding damage.
- Improved observability: Checks encourage useful logs, metrics, alerts, and diagnostic context for operational teams.
- Reduced regression risk: Repeatable test cases help verify that maintenance changes do not weaken established behavior.
Benefits depend on disciplined interpretation. A green result is evidence about the tested scenarios, not proof that every possible condition has been covered. Teams should review whether tests represent realistic usage, whether thresholds reflect user needs, and whether monitoring after release can detect conditions the test environment did not reproduce. This balanced view helps quality assurance support dependable engineering without overstating what any individual test can establish.
Trust, Security, and Integrity in Reliability Testing
Reliability and security overlap whenever faults, malformed input, or resource pressure could expose sensitive data or weaken access controls. Test environments should use approved datasets, protect credentials, restrict access, and avoid creating unnecessary copies of personal information. When a test simulates a failure, teams should define its scope and rollback method in advance. Logs and reports need enough detail for diagnosis, but they should not disclose secrets or sensitive values. Applying these safeguards makes reliability evidence more trustworthy and reduces the risk that testing itself creates an incident.
Quality assurance findings should be traceable from requirements to scenarios, results, defects, fixes, and retests. Record who ran a check, when it ran, which build and configuration were used, and any limitations that affected interpretation. A review process can confirm that high-severity findings are resolved or explicitly accepted by authorized stakeholders before release. MAGICQA20261111T remains only a temporary publication test label in this article; it should not be presented as a security standard, independent audit, or assurance certificate.
Why Choose a Measured Reliability Check for Quality Assurance
A measured approach is appropriate when a team needs evidence that software can sustain expected use, preserve correct data, and recover from foreseeable disruptions. Before adopting a check, confirm that it addresses a defined risk, has clear pass and fail criteria, can be run safely, and produces evidence that engineers can act on. Also assess the cost of maintaining the scenario: tests that are brittle, poorly documented, or disconnected from user behavior may create noise rather than confidence. Strong reliability assurance combines targeted automation, deliberate exploratory testing, and operational monitoring.
For a practical decision, prioritize workflows by impact, establish a baseline, and add scenarios for the failures most likely to affect users or data. Keep test conditions repeatable, review trends rather than isolated numbers, and retest fixes under the original conditions. This gives teams a defensible way to manage uncertainty while recognizing that software reliability is continually assessed, not permanently guaranteed by one successful run. Used in this context, MAGICQA20261111T simply marks the publication test and has no bearing on test outcomes or product quality.
SABÍAS QUE:
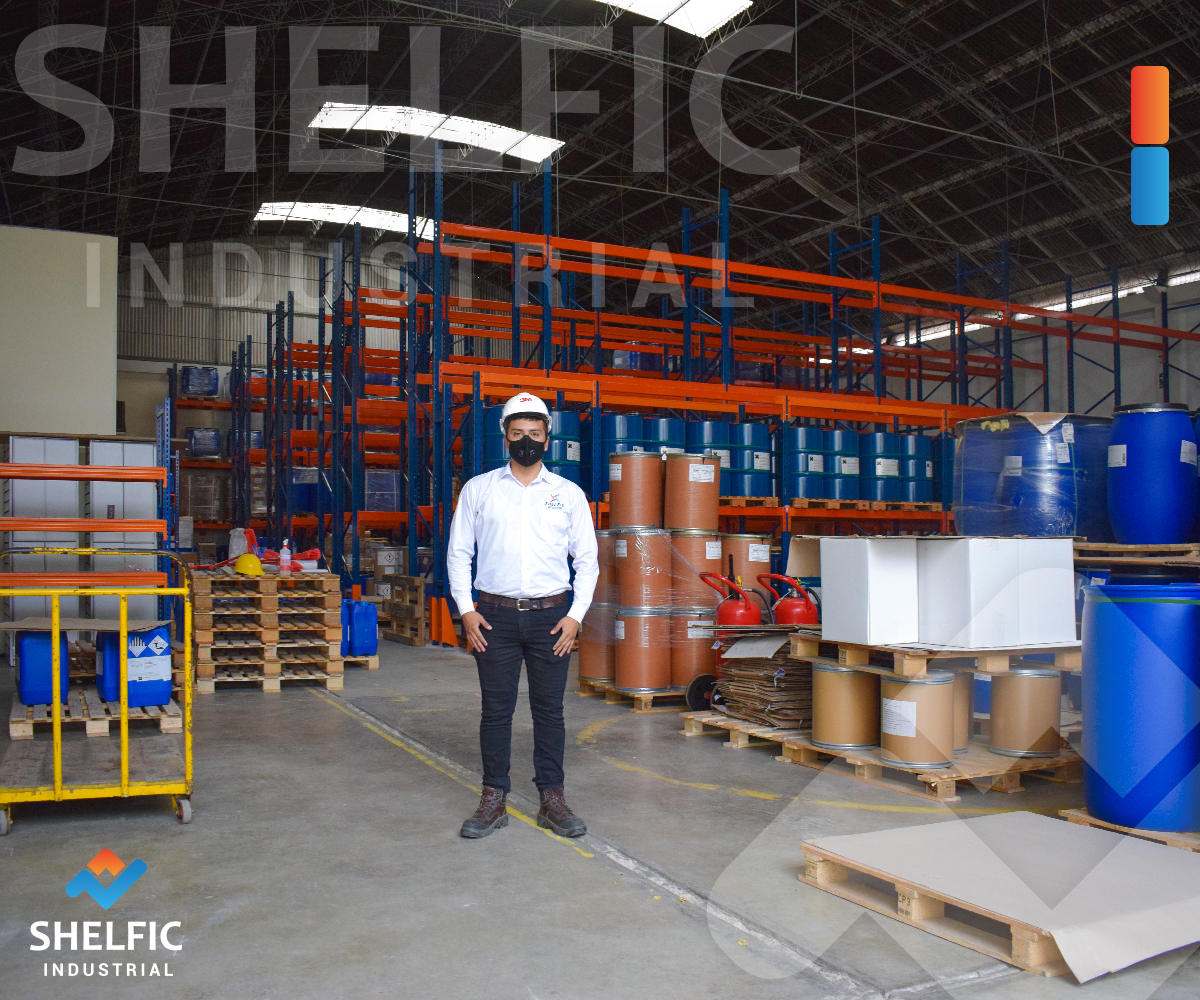
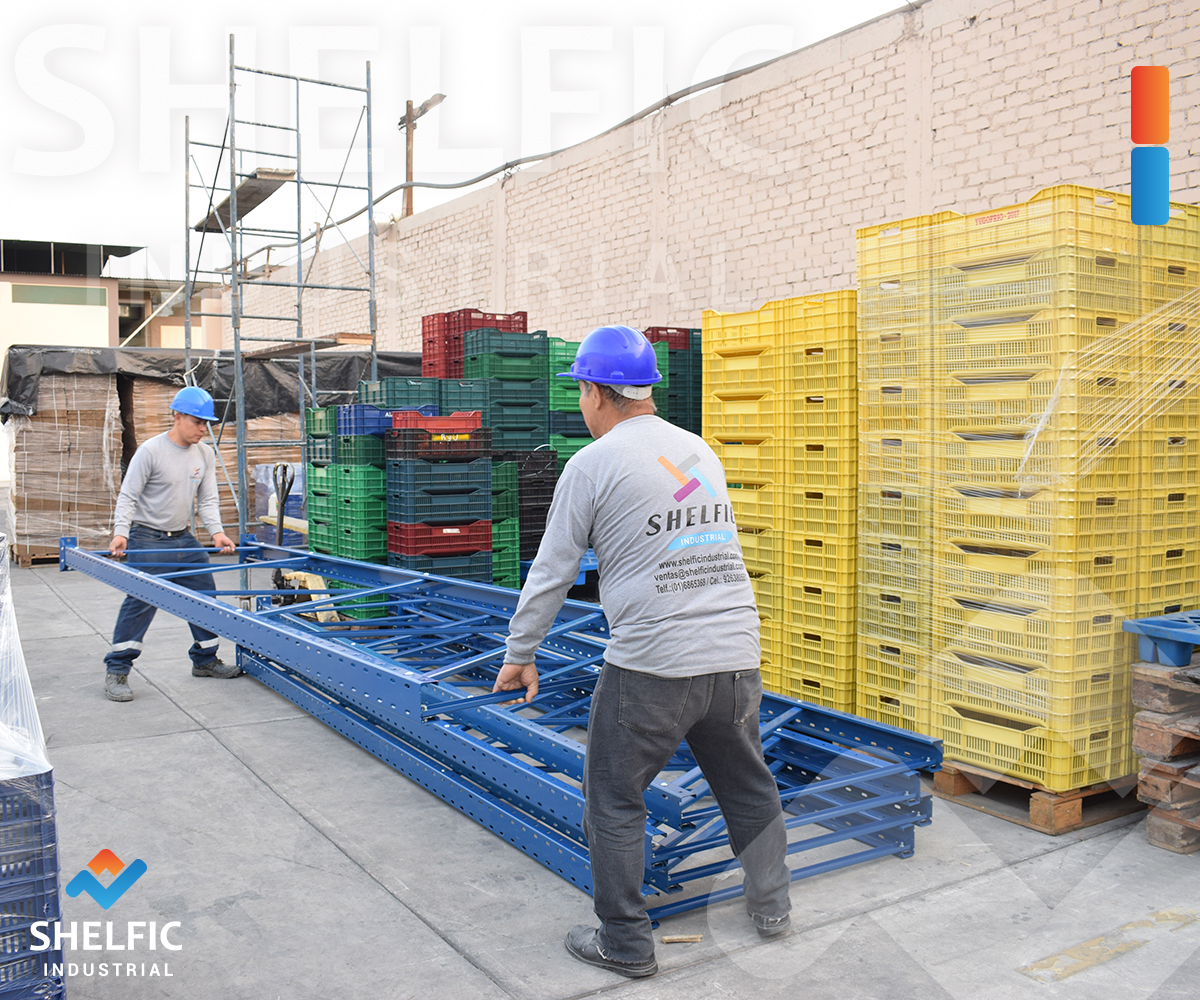
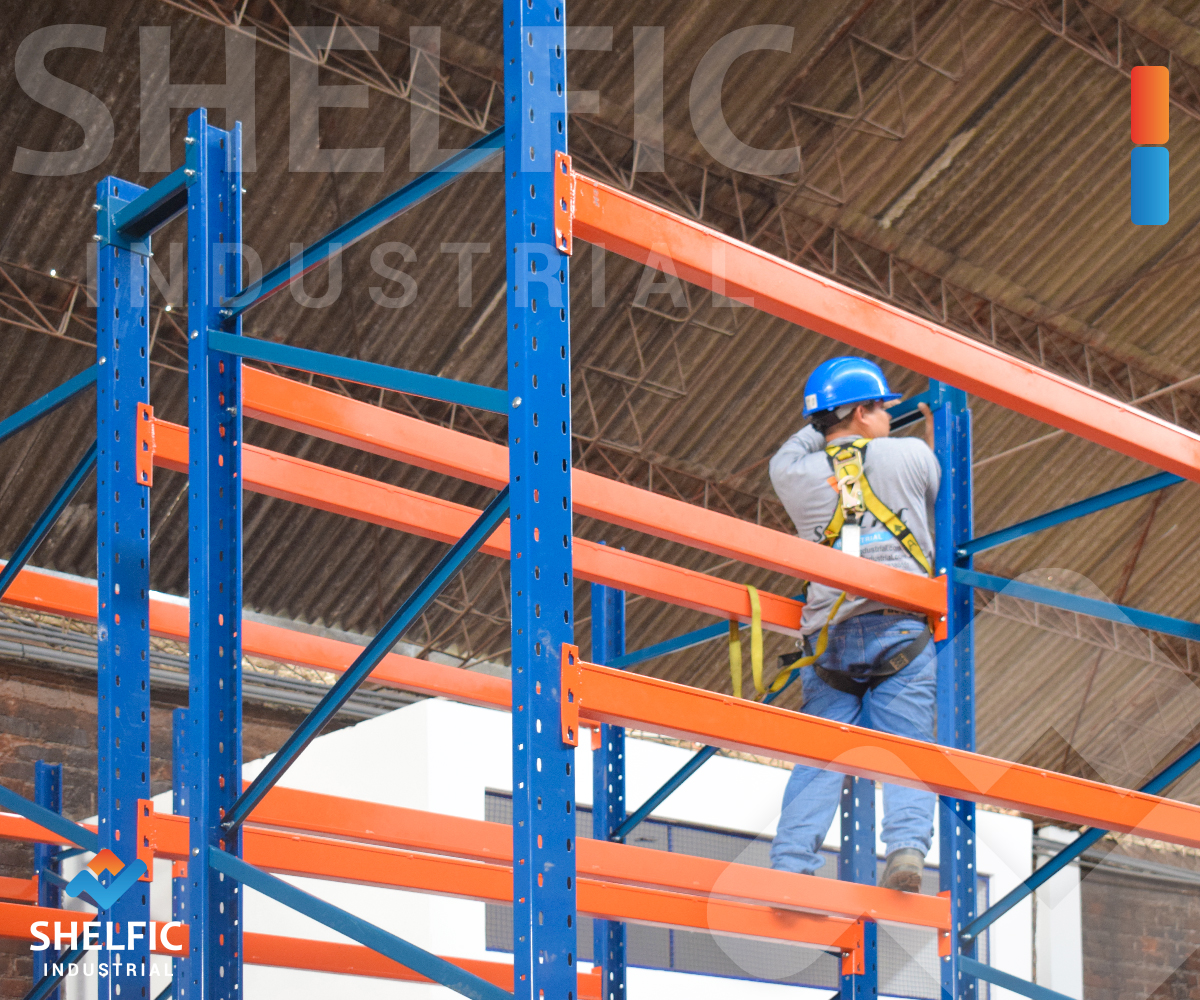
Si, lo que quieres es una asesoría completa 100% profesional. Nosotros vamos hasta tu local, y te ayudamos.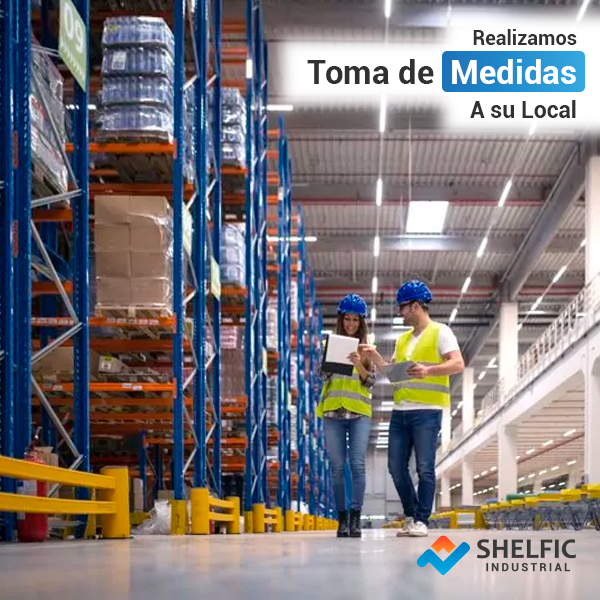
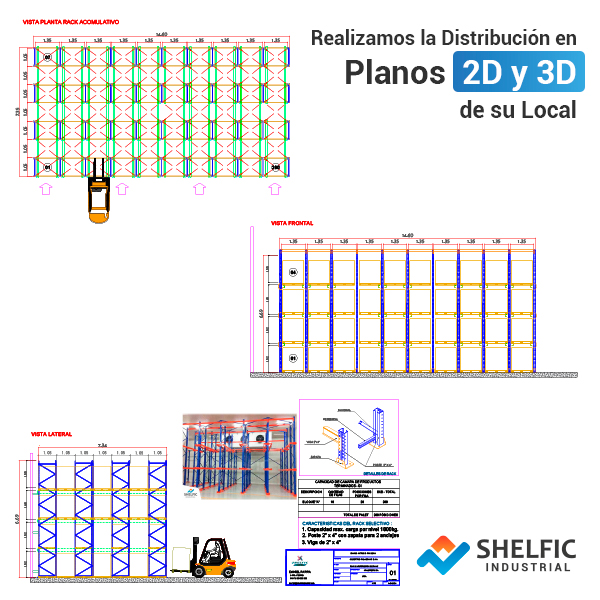
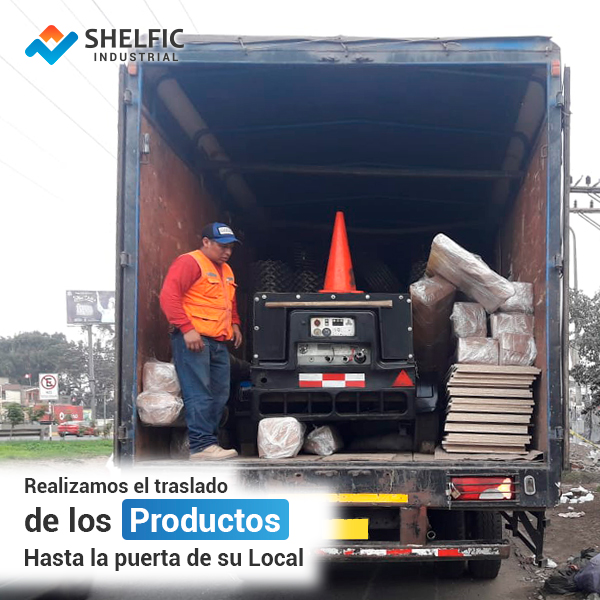
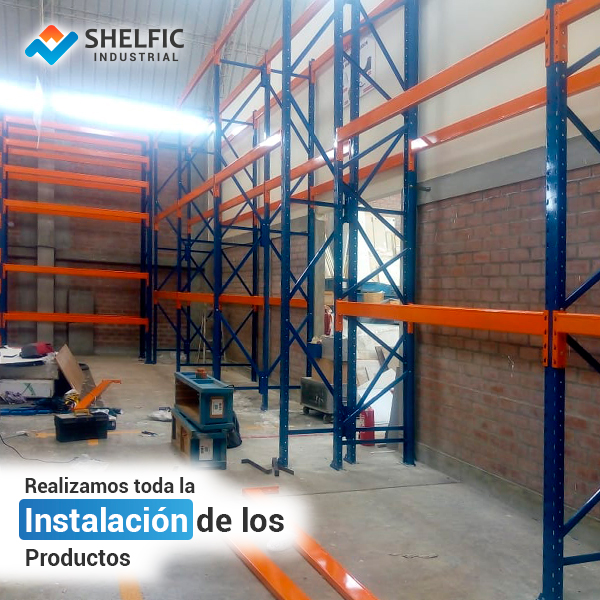
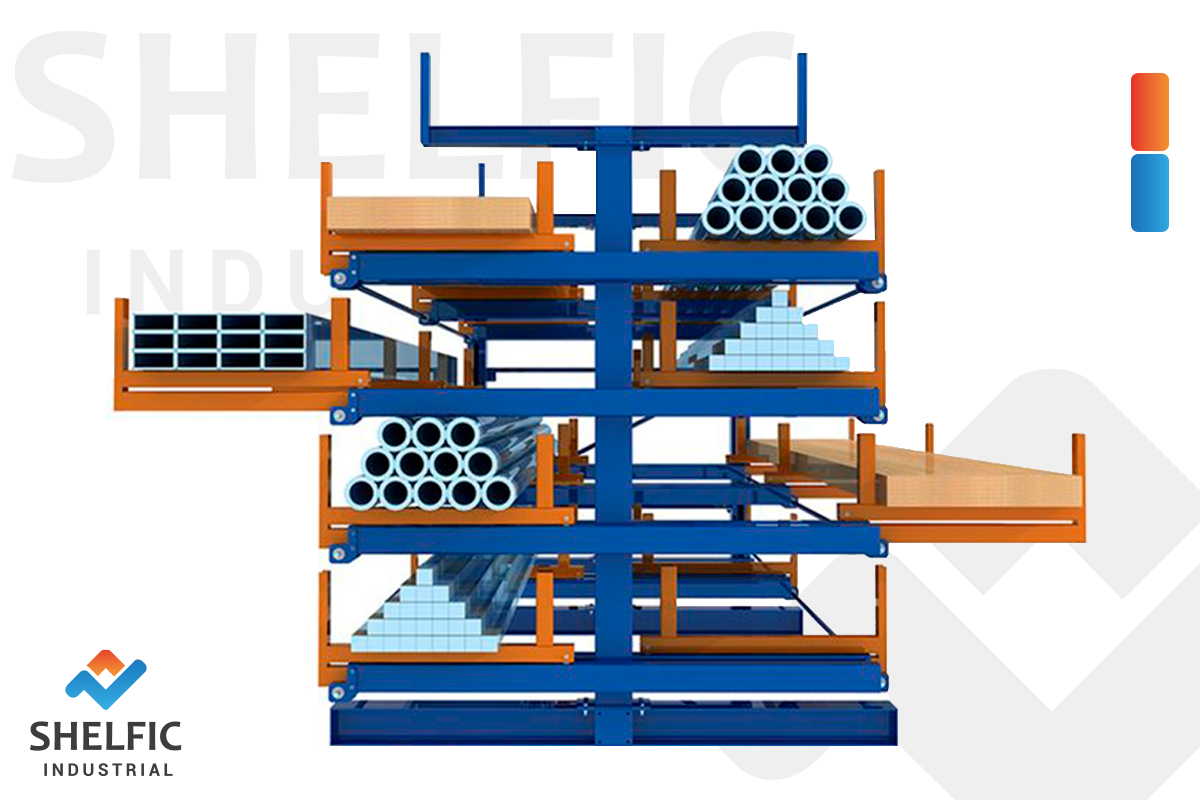
Estantería para Optimizar Espacios:

Por la Implementación de su Proyecto con Nosotros, le Ofrecemos
Servicios Exclusivos Completamente GratisAdemás, contamos con muchos Beneficios y Promociones.